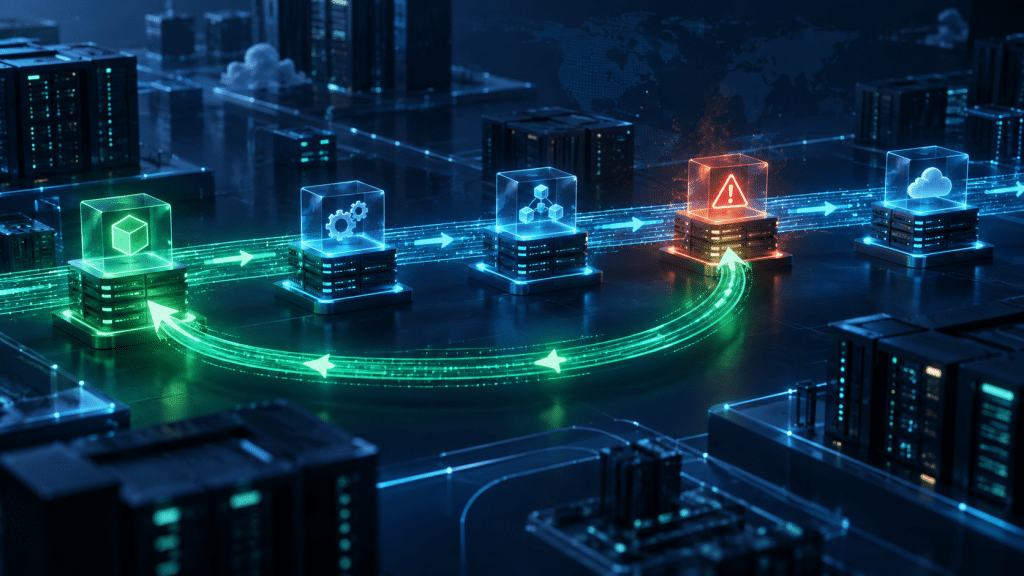
Every release carries risk. A team can test in staging, review the code, and run the deployment pipeline successfully, yet still introduce a regression, broken integration, or unexpected performance issue in production. When that happens, the team needs a reliable way to restore service.
A deployment rollback returns an application or service to a previously known-good state after a problematic release. Done well, it can turn a production incident into a brief disruption. Without a tested rollback plan, the same issue can become a prolonged outage while teams diagnose and repair it under pressure.
This guide explains how deployment rollbacks work, what can trigger them, which strategies teams can use, and why databases often make rollback more complicated.
What Is a Deployment Rollback?
A deployment rollback is the process of reverting a deployed application or service to a previously known-good version after a release causes a defect, regression, or failure. It is a recovery action rather than a permanent fix. The immediate goal is to restore stability while the team investigates the underlying problem.
A rollback moves backward to an earlier version. A roll-forward moves ahead by deploying a new version that corrects the defect, often through a hotfix. Teams usually roll back when the impact is significant, the cause remains unclear, or a safe fix will take time. They may roll forward when the problem is narrow, well understood, and faster to correct than to reverse.
Rollback can also refer to other operations. A database rollback may undo a transaction, while a configuration rollback restores an earlier configuration. A full deployment rollback may involve application code, configuration, infrastructure, and data. Because these components do not all revert equally easily, teams must plan beyond simply redeploying an older build.
What Triggers a Rollback?
Teams can trigger a rollback automatically or manually. Mature deployment processes usually support both because monitoring can identify technical failures quickly, while people can recognize business or workflow problems that dashboards may miss.
1. Automatic Rollback
An automatic rollback begins when a monitored signal crosses a predefined threshold. Common triggers include rising error rates, failed health checks, increased latency, or an unusual drop in successful transactions. The deployment system responds immediately, which can reduce recovery time and limit the number of affected users.
This approach depends on strong observability. Teams need relevant metrics, meaningful health checks, and thresholds that distinguish a genuine release failure from ordinary noise. Otherwise, the system may overlook a serious issue or reverse a healthy deployment unnecessarily.
2. Manual Rollback
A person initiates a manual rollback after identifying a problem that automation did not catch or deciding that a release is unsafe. For example, an application may report normal latency and error rates while calculating prices incorrectly, skipping an approval step, or displaying stale information.
Clear decision criteria help teams act quickly. A runbook should define who can authorize a rollback, which types of impact justify one, and when a roll-forward makes more sense. Teams should establish these rules before an incident rather than debate them while users experience the problem.
Four Common Deployment Rollback Strategies
The best rollback method depends on the application architecture, release process, recovery time objective, and cost of maintaining fallback capacity. Many organizations use more than one strategy across their application portfolio.
1. Redeploy a Previous Artifact
The simplest strategy is to redeploy the last known-good image, package, or build from an artifact repository. This method requires little specialized infrastructure and works especially well for stateless applications. Recovery usually takes about as long as a standard deployment.
Reliable artifact retention makes this strategy possible. Teams should preserve several previous builds, label known-good versions clearly, and keep their deployment instructions reproducible. If the pipeline overwrites or aggressively removes old artifacts, the fallback may not exist when the team needs it.
2. Switch Back in a Blue-Green Deployment
Blue-green deployment maintains two parallel environments. One serves production traffic while the other receives the new version. After validation, the team routes traffic to the updated environment. If the release fails, the team sends traffic back to the environment that still runs the previous version.
This approach offers very fast recovery because the known-good environment remains available. However, maintaining two production-capable environments increases infrastructure costs and operational complexity. Organizations often reserve blue-green deployment for systems with strict availability requirements.
3. Disable a Feature Flag
When developers place new behavior behind a feature flag, the team can disable that behavior without redeploying the application. This makes feature flags useful for isolating a problematic capability while leaving the rest of the release in place.
Feature flags only protect changes designed to use them. Teams must add the flag before deployment, test both states, and manage old flags so they do not accumulate into long-term technical debt. A flag also may not help when a release changes shared infrastructure or data in an incompatible way.
4. Abort a Canary Release
A canary release directs a small share of traffic to the new version before expanding the rollout. If monitoring reveals a problem, the team stops promotion and routes the canary traffic back to the previous version. This limits the blast radius because most users never encounter the faulty release.
Canary releases work particularly well with automated analysis. The same performance and reliability signals that determine whether to increase traffic can also trigger an abort. Success depends on representative traffic, reliable monitoring, and clear promotion thresholds.

Why Database Rollbacks Are More Difficult
Application code is often straightforward to replace because the deployment artifact is immutable. Databases preserve state, including changes created while the faulty version was live. Reverting application code does not automatically restore the earlier schema or undo new and modified records.
Schema changes create another compatibility risk. If a migration drops a column, changes a data type, or rewrites stored values, the previous application version may no longer understand the database. Some operations also destroy information that a rollback cannot recover without a backup or a separate restoration process.
Teams can reduce this risk with the expand-and-contract pattern. First, they expand the schema so both the old and new application versions can use it. For example, they may add a new column while retaining the old one. Next, they deploy and validate the new code. Only after the rollback window closes do they remove the old structure.
For critical migrations, teams should also define backup, restoration, and reconciliation procedures. A restored backup may lose legitimate transactions created after the backup, so teams need a plan for preserving or replaying that data. The safest approach depends on the system’s architecture and recovery objectives.
How to Build a Reliable Rollback Process
A rollback plan must work under real incident conditions, not just on a diagram. The following practices create the operational foundation for dependable recovery.
1. Retain Known-Good Artifacts
Store previous deployment artifacts, configuration versions, and infrastructure definitions for an established period. Mark known-good releases clearly so responders do not have to reconstruct the target version during an incident.
2. Maintain Release and Environment Visibility
Keep a current record of what version runs in each environment, when it was deployed, and which configuration and database changes accompanied it. Strong release management gives teams the context they need to select and coordinate the right recovery action.
3. Define Triggers and Decision Rights
Document the metrics, business symptoms, and severity levels that warrant a rollback. Assign authority to specific roles so responders know who can make the decision and who must receive status updates.
4. Create and Test Runbooks
Write the rollback steps for each service, including validation checks and escalation paths. Test those runbooks in production-like environments and rehearse database compatibility scenarios. Regular exercises reveal missing permissions, outdated commands, and hidden dependencies before an actual failure does.
5. Confirm Recovery
Do not treat a successful deployment command as proof of recovery. Check service health, critical user journeys, data integrity, and downstream integrations. Continue monitoring after the rollback in case delayed failures appear.
Make Rollback Part of Release Planning
Rollback works best when teams design it into the release process. Retained artifacts, reliable telemetry, clear ownership, compatible database changes, and tested runbooks turn reversal into a controlled operation rather than an improvised response.
Enov8 connects release plans with systems, environments, versions, dependencies, readiness checks, and implementation tasks. That visibility helps enterprise teams document rollback steps, understand what changed, and coordinate recovery across complex delivery landscapes. Learn more about Enov8’s enterprise release management solution.