Testing is an integral and vital part of creating software. In fact, test code is as important as your production code. When you create test code, you need to create test data for your code to work against.
This post is about the different types of test data that are used in software testing. I’ll elaborate on each type and explain what test types are used in which scenarios.
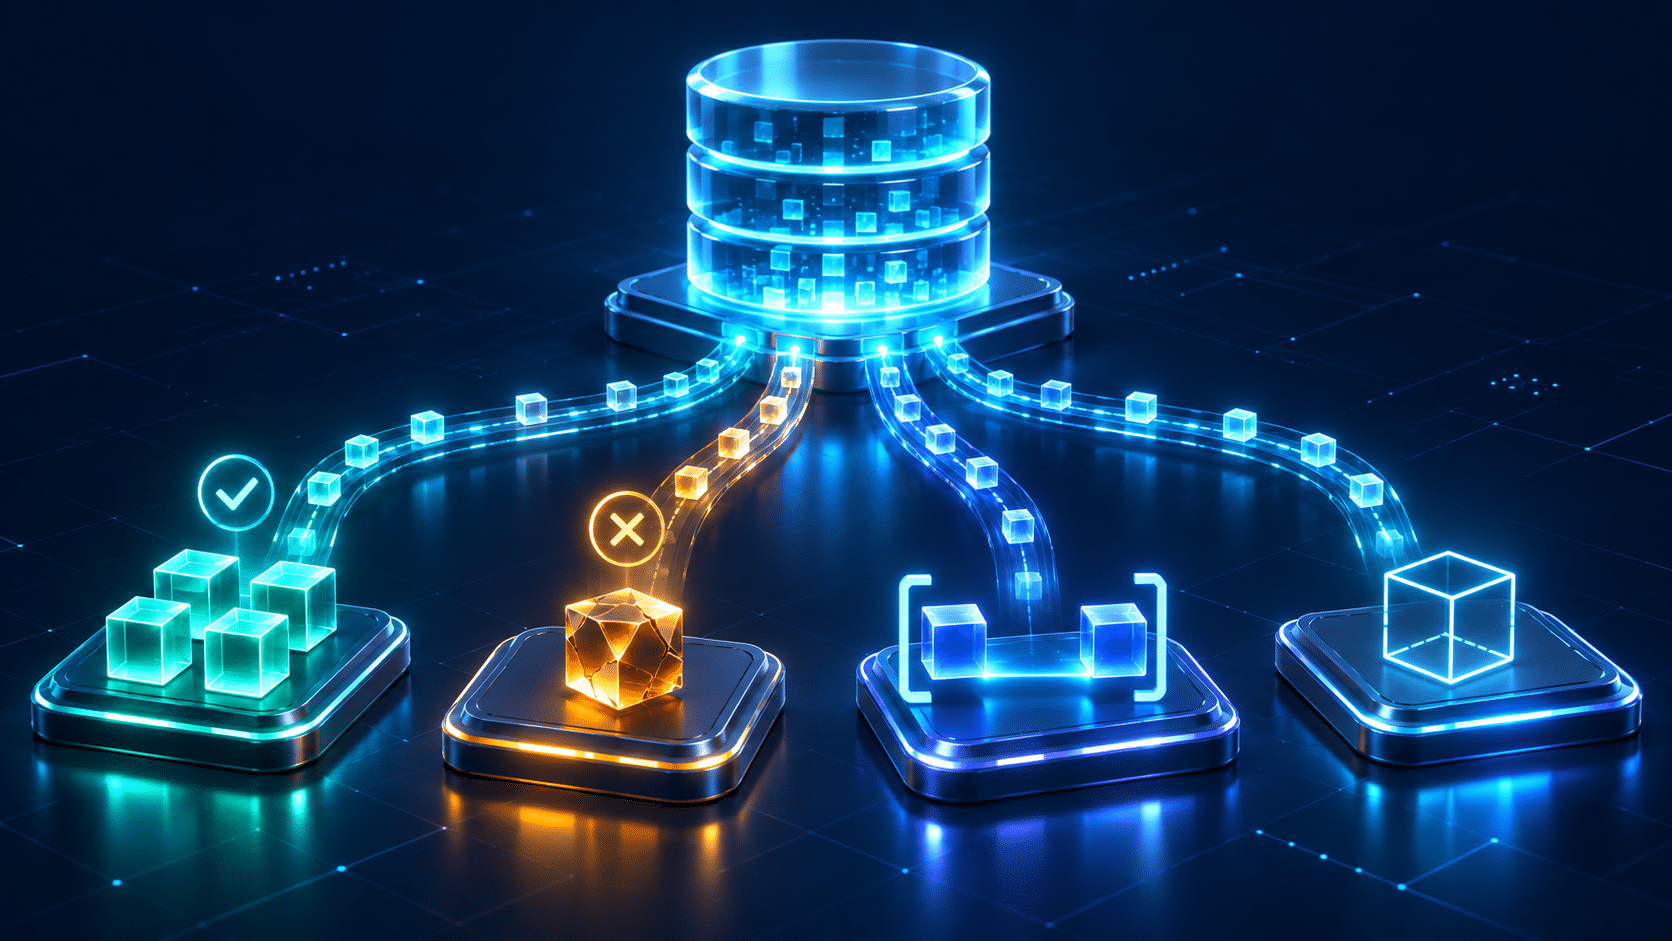
Types of Test Data
Let’s take a look in detail.
1. Valid Test Data
As the name implies, valid test data is the data that your program expects and should operate on. You want to create tests with valid data to make sure that the program functions as expected when using data that meets your integrity and validation criteria.
For instance, if you do integration tests as part of a login use case, you will want to provide a correct username and password (in this scenario, valid data) and check that the user is logged in properly.
Test code is as important as your production code.
2. Invalid Test Data
It’s important to make sure that your program knows how to handle data that doesn’t conform to your data integrity and validation requirements.
First things first: your application must not process invalid data as valid data. The code should identify that this data is invalid and handle it accordingly. This may involve displaying an error message, adding an entry to a log file, or returning a specific HTTP status code.
Depending on the application, invalid data can lead to different outcomes:
- Preventing an action until valid data is entered. For instance, on a login page, the user can’t continue without providing valid credentials. Likewise, entering text into a calculator’s numeric field should produce a validation error rather than a calculation.
- Stopping execution. For example, if a database migration encounters corrupted data, it may need to stop, report the problem, and exit rather than continue processing.
- Limiting functionality. For example, if a game requires valid payment details to unlock its full version, submitting invalid details may leave the user with access only to the demo.
In each case, your tests should confirm that the application handles invalid data as intended and gives the user a relevant explanation.
3. Boundary Test Data
When we write code, there are certain limitations on the values we can use that stem from the fact that we run on physical hardware. Physical hardware has its objective capacity limitations.
For example, a PC has only so much RAM to use. In addition, the CPU’s assembly language, the language we write code in, and the compiler have their own sets of restrictions.
Integer types have minimum and maximum values that depend on their size and implementation. We can’t store a string in an integer variable in Java, and so forth.
Boundary test data is intended to check how our code handles values that are close to the maximum upper limits or exceed them.
Developers usually write code with values in mind that are far from the boundaries of the machine, language, and compiler. However, in many cases, values that are near or equal to the boundary are considered valid input and should be handled as such.
In addition, values that exceed the boundaries should be handled gracefully (i.e., with a dedicated error message) and not make the whole program crash (case in point: Microsoft Windows’s “blue screen of death”). Testing boundaries is especially important in the context of load and stress tests when we want to check how the machine performs under high load.
Likewise, boundary tests are especially important in the context of contract tests. Those are usually API tests that check that the API responds properly to a given input. By checking values at and around input boundaries, we can catch validation errors that tests using typical values may miss.
4. Absent Test Data
There is another possibility too: when the program gets no data at all rather than valid or invalid data. It just isn’t there. We refer to this as absent data.
Let’s examine a case when a program expects to fetch some user data from the database to validate credentials against (like in the aforementioned example), but the database doesn’t contain any user data and returns an empty result set.
This is a test case we should be aware of and implement.
As I’ve mentioned, sometimes the data required for the proper functioning of the code just isn’t where we expect it to be, whether in a database, an external service, or some other source.
As in the case of invalid data, we should make sure that our code can handle such situations gracefully. And no, a message that says “Something is wrong” is not considered proper handling.
Proper handling depends on why the data is missing. The application might display an empty state, request the missing information, use a documented default, or retry a failed request.
In the meantime, you need to return to the client a relevant message that helps them solve the problem if possible.

Types of Test Data With Examples
Let’s put these types of test data together in one example. Suppose you’re testing an online store that allows customers to order between 1 and 10 units of a product.
You need to check that customers can place an order, but you also need to know what happens when they enter something unexpected.
- Valid test data: An order for 4 units. The application should accept the quantity.
- Invalid test data: An order for −3 units or the word “four.” The application should reject the input and display a relevant validation message.
- Boundary test data: Quantities of 0, 1, 2, 9, 10, and 11. The application should accept values within the permitted range and reject those outside it.
- Absent test data: No quantity is supplied. The application should request a quantity or apply a documented default.
Notice that boundary data includes values around both the minimum and maximum permitted quantities. These limits can come from business requirements, such as an order limit, as well as technical restrictions.
Also, the categories can overlap. A quantity of 10 is both valid data and boundary data. What matters is knowing which behavior each test is intended to check.
Ways to Generate Test Data
There are various methods available to generate test data for software testing, each with its own advantages and disadvantages.
1. Manual Generation
One method is manual test data generation, which involves entering data items manually. While this provides maximum control and granularity over the test data, it can be a time-consuming process.
2. Copying from Production
Another method is to copy existing data from production environments. This method can be faster than manual generation, but data security and cleanup may be concerns when importing sensitive data.
Many test data management tools on the market help you create test data for your test environments. For example, Mockaroo and equivalent tools allow you to generate random mock test data in support of software testing.
This can be a huge time-saver and go hand in hand with manual data creation if necessary. The other benefit is data security; by using fake test data, you avoid reusing sensitive data and the potential for data breaches.
3. Cloning
Data cloning is another way to generate test data, where an existing set of test data is copied and modified to create new test scenarios. This data cloning method can be useful when generating large amounts of similar data quickly, but it may not be suitable for testing unique scenarios.
Ultimately, the choice of method for generating test data will depend on the specific testing requirements and constraints.
Synthetic Test Data vs. Production-Derived Test Data
So far, we’ve looked at test data according to how the application should handle it. Another useful distinction is where the data comes from.
Synthetic test data is created specifically for testing. For instance, you might generate fictional customers, products, and orders. You can use it to build scenarios that are difficult to find in an existing database, such as a customer whose subscription expires during checkout.
Production-derived test data comes from an application’s live environment. It can provide realistic combinations of records, but sensitive information needs appropriate protection before the data is made available to testers.
A production subset contains selected records rather than a copy of the entire database. When preparing one, you need to preserve the relationships your tests depend on. An order without its associated customer or products may not be useful.
These source categories don’t replace valid, invalid, boundary, or absent data. You can generate synthetic data for any of those scenarios or use a protected production subset as a starting point.
How to Choose Test Data for Your Tests
The right test data depends on what you want to verify. Start with the expected behavior, then prepare the records and values needed to exercise it.
For a unit test, a few carefully chosen inputs may be enough. For an integration test, you may need related records across several components. Testing an order workflow, for example, could require a customer account, available stock, and payment details that are valid in the test environment.
Performance tests need data volumes and distributions that reflect the workload being tested. Repeating one identical record thousands of times may miss problems that appear with varied customer histories or order sizes.
For regression tests, prepare a known starting state that you can restore before each run. Otherwise, an earlier test might change or delete data that a later test needs.
Finally, record the expected result alongside each dataset. A collection of inputs is useful only when you can tell whether the application handled them correctly.
Conclusion
In Software Testing, it is important to create solid, functioning software. There are different types of test cases, and there are different test data types you need to prepare for each.
Since creating test data is time-consuming, you can use dedicated tools and services to help you with this task in addition to manually creating your test data.
For a broader understanding of Test Data Management, why not check out this TDM article on the Test Data Management lifecycle.
And why not have a look at Enov8’s Test Data Manager? A holistic Test Data Management tool covering all of the key Test Data & Data Security aspects, including Test Data Profiling (which finds your Personally Identifiable Information), Test Data Masking, Test Data Validation, Realistic Test Data Creation, Test Data Mining & Test Data Bookings.
Enov8 Test Data Management is an important addition to any organization’s software testing optimization and data security solutions.