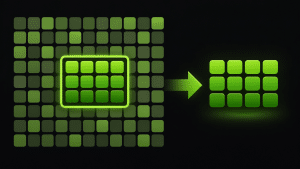
What Is Data Subsetting? Methods, Examples and Best Practices
Data subsetting extracts a smaller, referentially intact subset of production data for testing. Learn how it works, the main methods, a worked example and how to choose a tool.
Data subsetting extracts a smaller, referentially intact subset of production data for testing. Learn how it works, the main methods, a worked example and how to choose a tool.
PeopleSoft holds some of the most sensitive data an organization keeps: Social Security numbers, salaries, home addresses, and health records for employees or citizens. In production, that data sits behind tight controls. In dev, test, and UAT, it often doesn’t. Data masking helps close that gap, and PeopleSoft gives you some tools to do it. […]
Many teams copy production data into non-production environments to move fast, and that is exactly where sensitive data can end up exposed. This guide explains how K2view approaches data masking, why its entity-based model matters, and what to weigh before you decide it covers your needs. What Is K2view Data Masking? K2view data masking replaces […]
Enterprises are generating more data than they can see. You can’t govern, secure, or use data you can’t find. That is the gap data discovery tools exist to close, and this guide walks through what they do, the features that separate them, the leading options, and how to pick one. What Are Data Discovery Tools? […]
Data masking and tokenization both protect sensitive data by replacing it with something safer to handle. They solve different problems, though, and choosing the wrong one adds cost or leaves a gap. This post defines each clearly, sets them side by side on the criteria that drive the decision, and gives you a framework for […]