Many teams copy production data into non-production environments to move fast, and that is exactly where sensitive data can end up exposed. This guide explains how K2view approaches data masking, why its entity-based model matters, and what to weigh before you decide it covers your needs.
What Is K2view Data Masking?
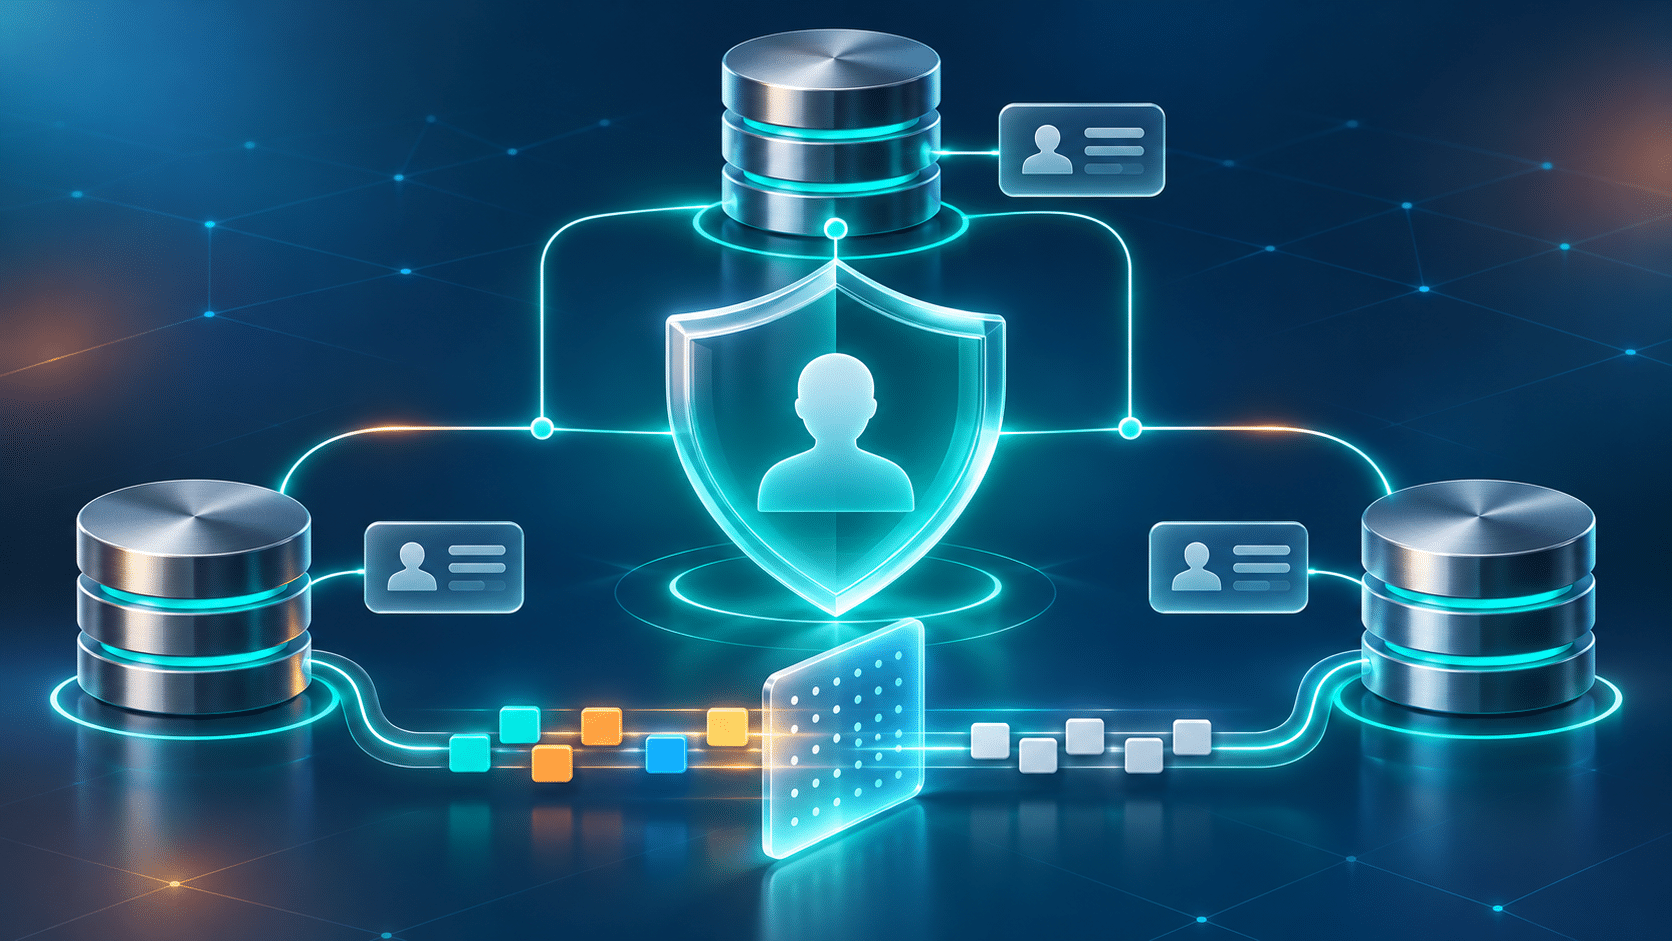
K2view data masking replaces sensitive values with realistic but fictional ones while preserving the relationships between data associated with a business entity. The goal is simple to state and hard to do well: the data has to be safe and still behave like the original.
K2view positions its masking around a specific idea, the business entity. Instead of treating masking solely as a field-by-field operation on isolated tables, it organizes data by the entity it belongs to, such as a single customer or a single order, and applies masking within that context.
Entity-level consistency matters because sensitive data rarely lives in one place. The same customer identifier appears across billing, support, and fulfillment systems. If each system masks that identifier independently, the links between them can break. Masked values need to stay consistent across related tables so that primary key and foreign key relationships survive.
How K2view’s Entity-Based Masking Works
K2view organizes data into business entities, each held in its own small, self-contained store: think one logical micro-database per customer or order. Masking rules transform individual fields within this entity-based structure, allowing related data to be handled together.
Applying rules this way helps maintain consistency across systems. When a value needs to match across related records, the masking configuration must produce consistent replacements. Deterministic masking supports this requirement: the same input produces the same output within the configured masking scope.
As Enov8’s guide to data masking explains, consistent replacements help preserve referential integrity for integration testing.
That design addresses a common failure in poorly coordinated masking implementations. Mask a foreign key in one table without masking its match elsewhere, and joins stop resolving. Entity-based masking helps keep those relationships intact, although the rules and relationships still need to be configured correctly.
This also supports test data integrity. Masked test data is only useful if it still behaves like real data. Masked values must satisfy relevant business rules and validation requirements: account numbers may need to keep their length, and credit card test values may need to pass a Luhn check.
Miss those requirements, and applications can fail in testing or analytics can come back distorted. Consistency and validity together are what make a test meaningful.
Before implementation, confirm the masking configuration, supported sources, and validation behavior against K2view’s documentation and your environment.

Where K2view Data Masking Fits Well
Entity-based masking is particularly useful where data is spread across many interrelated systems. A few scenarios map to it cleanly.
1. Complex Enterprise Applications With Many Interrelated Tables
Large platforms like enterprise HR or ERP systems spread a single person’s data across dozens of related tables. Most organizations also run hybrid environments mixing relational databases, document stores, and cloud-native platforms. Applying consistent masking logic across all of them is a real hurdle. Masking by entity is designed to help manage that spread.
2. Non-Production and Sandbox Environments
Development, testing, staging, and training systems can expose sensitive data when teams copy production datasets into them. Broad access to these systems increases the risk. Masking real employee or customer data before it lands there helps reduce that exposure. Access controls and validation remain necessary to confirm the resulting dataset is appropriate for its intended use.
3. Organizations With a Broader Data Platform Strategy
Masking may be one part of a wider data product or data platform approach. In that setting, entity-based masking fits the organizing model the rest of the platform already uses. Related records can be handled together rather than through disconnected masking jobs. The practical benefit depends on how well the entity model reflects your applications and their dependencies.
Limitations and Gaps to Know
Entity-based masking is useful, but no masking approach solves everything. Treat the categories below as things to verify against your own environment rather than assumed shortcomings of any one product.
1. Configuration Still Takes Work
A platform like K2view can help teams apply consistent masking across enterprise data. But the rules still have to be designed and configured carefully. The tool does not remove the need to decide what counts as sensitive or how each field should be transformed. Teams also need to validate the results against business rules and testing requirements.
2. Unstructured Data Needs Separate Validation
Finding and classifying sensitive data across PDFs, images, and free text presents different challenges from masking structured fields. K2view advertises support for structured and unstructured data, so this should not be treated as a missing capability. Instead, confirm support for your specific formats, languages, and sensitive-data patterns. Test representative samples before relying on the results.
3. Masking Alone Is Not Test Data Management at Scale
Provisioning, subsetting, and environment management are separate problems from transforming values. Subsetting, which extracts smaller datasets while preserving the relationships between records, is its own technique, distinct from masking.
K2view’s broader test data management offering includes capabilities beyond masking, including subsetting and provisioning. Evaluate those capabilities against your workflow rather than assuming they are absent. If your bottleneck is standing up and tearing down many environments, assess the complete lifecycle.
How Enov8 Fits Into a Data Masking Strategy
The broader lifecycle is also where Enov8 fits into a data masking strategy. Enov8’s test data management capabilities include sensitive-data discovery, masking, validation, and provisioning. Depending on your existing tools and requirements, it may serve as an alternative or support a wider environment and data management approach.
That lifecycle covers more than transforming values. Enov8 maps the main TDM techniques—masking, subsetting, synthetic data generation, and database virtualization—to distinct capabilities, and treats provisioning as part of the pipeline.
In practice, that means preparing an appropriate dataset or clone for a test run, then refreshing, resetting, or removing it afterward. Connecting that workflow with environment management helps teams coordinate access and availability.
Virtualization changes the math on how much data teams need to copy and store. Enov8 Virtualize provides lightweight, isolated database clones, giving each team or pipeline its own working copy instead of a full physical duplicate.
Subsetting can reduce the number of records that need masking, while virtualization reduces duplication and speeds up provisioning. Neither technique replaces masking. Any source data or clone containing sensitive information still needs appropriate protection before teams receive access.
The compliance point ties it together. Non-production environments still need appropriate safeguards for sensitive data. Masking or synthesizing data before it reaches a development or testing pipeline can help reduce exposure, alongside access controls, validation, and retention policies.
The practical decision is whether your tools can deliver safe, usable data throughout its lifecycle. Evaluate masking quality, cross-system consistency, provisioning, and environment coordination together.
To see how this works in practice, explore how Enov8 complements and extends your test data management strategy.