Data engineers, ML engineers, and QA teams run into the term “synthetic dataset” and want a straight answer before deciding whether it fits their workflow. This guide covers what it is, how it’s made, its types, its benefits and limits, and where it shows up in practice.
What Is a Synthetic Dataset?
A synthetic dataset is a collection of artificially generated data designed to resemble real-world data for a particular use case.
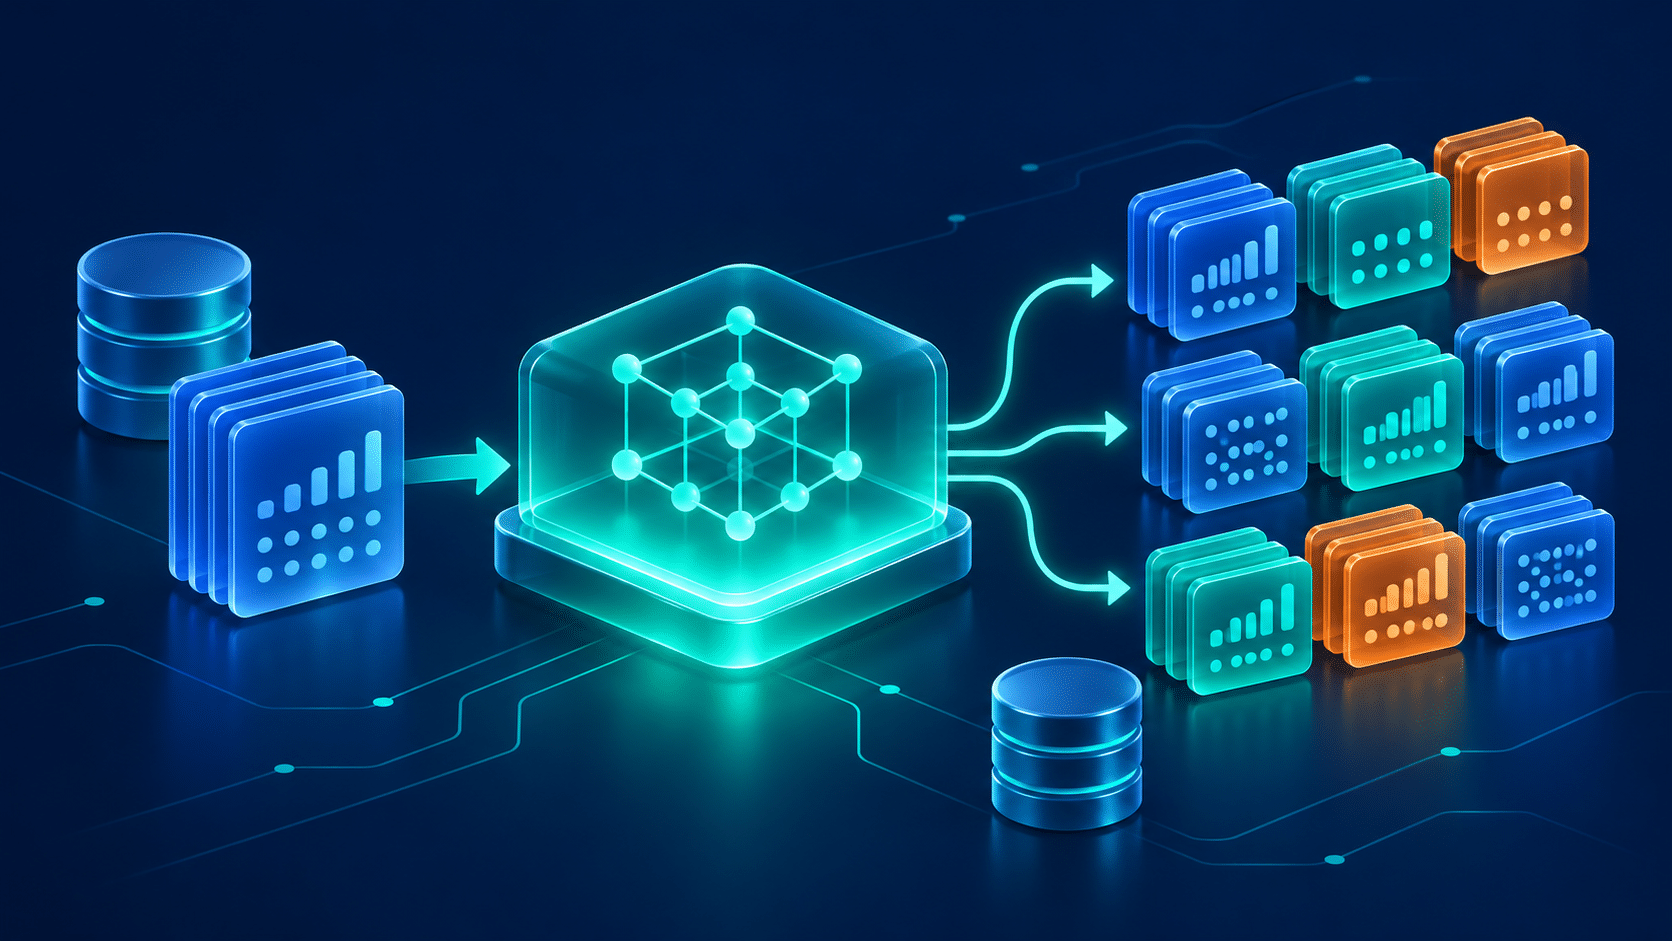
That distinction does most of the work. Real data is recorded from actual activity: a transaction a customer made, a reading a sensor logged, a form a user filled in. Synthetic data is produced the other way around. An algorithm generates records using predefined rules, statistical distributions, simulations, or patterns learned from real data.
The result is designed to look and behave like the real thing for its intended purpose. A synthetic customer table has the right columns, plausible values, and realistic relationships between fields. Fully synthetic records are intended to avoid a one-to-one tie back to actual people, but their usefulness and privacy still need to be validated.
Types of Synthetic Data
Synthetic data comes in two broad forms, and the difference comes down to how much real data sits underneath.
Partially Synthetic Data
Partially synthetic data starts from real records and replaces selected fields with synthetic values. The order dates, product categories, and quantities might stay as they were, while names, account numbers, and addresses are swapped for generated stand-ins.
Teams choose this approach when they need to preserve the real structure and most real values but cannot expose fields that carry privacy or compliance risk. Retained fields still need to be assessed for their potential to identify individuals.
Fully Synthetic Data
Fully synthetic data contains entirely generated records rather than real records with selected fields replaced. A generator can learn the patterns of a real dataset and then produce new data that matches those patterns statistically. Alternatively, it can use rules or simulations without access to real records.
Teams choose this when privacy requirements are strict, when they need more data than they actually have, or when real data is unavailable for development and testing.
How Is Synthetic Data Generated?
There are several approaches, and they trade off simplicity against fidelity. The right one depends on how complex your data is and how closely the synthetic version needs to match the original. The approaches below overlap: deep learning methods are also model-based methods.
Statistical Distribution Methods
A relatively simple approach models the statistical properties of a real dataset and samples new values from those distributions. You measure the mean, spread, and shape of each field, then draw fresh values that follow the same curves. It is fast and transparent, and it works well when the relationships between fields are simple.
Model-Based Methods
Other model-based methods go a step further by learning the patterns and correlations in real data, then generating new records that honor those patterns. Instead of treating each field on its own, the model captures how fields move together, so a generated record is internally consistent. This suits data where the relationships between columns matter as much as the columns themselves.
Deep Learning Methods (GANs, VAEs, Transformers)
For complex, high-dimensional data, deep learning offers more flexible generators. Generative adversarial networks (GANs) pit a generator against a discriminator so the generated data becomes harder to distinguish from the real thing. Variational autoencoders (VAEs) compress data into a learned latent space and sample from it to produce new examples.
Transformer-based models can generate sequential and structured data, capturing long-range patterns that simpler methods may miss.
Standing up these pipelines from scratch is real engineering work. Enov8 DataFactory supports synthetic test data generation so teams can produce realistic datasets without building and maintaining their own generation stack. That lets data and QA teams focus on using the data rather than on the machinery that creates it.

Benefits of Using a Synthetic Dataset
The appeal of synthetic data comes down to a few concrete gains that real data cannot always offer.
1. Scalable Generation
You are no longer capped by how much real data you happen to have. If a test or a model needs a million records, you can generate a million, subject to available computing resources. The important check is whether those records add useful variety rather than repeating the same narrow patterns.
2. Privacy Protection
Synthetic records can reduce the need to share real personal information. That can help teams develop, test, and collaborate with less exposure to sensitive source data. However, generators trained on real records can reproduce sensitive details, so privacy checks remain necessary before sharing a dataset.
3. Bias Reduction
When a real dataset over-represents some groups and under-represents others, you can generate additional examples to help address the imbalance. This gives teams more control over the cases represented in training and testing. It does not automatically remove bias, and the resulting model still needs to be evaluated across relevant groups.
Challenges of Synthetic Data
Synthetic data is not free of trade-offs. Quality control and stakeholder understanding are two challenges teams need to address.
1. Quality Control
Synthetic data has to reflect the distributions, relationships, and scenarios that matter to its intended use. A model trained on data that drifts from reality may perform poorly on real inputs. Teams should validate statistical similarity, business rules, rare cases, and downstream performance rather than judging quality by appearance alone.
2. Stakeholder Confusion
Teams new to the concept sometimes conflate synthetic data with fabricated or unreliable data, which makes early buy-in harder. Clear documentation should explain how the dataset was generated, what it was validated for, and where its limits lie. That gives stakeholders a practical basis for deciding whether it is suitable for their work.
Synthetic Dataset Examples
The clearest way to understand synthetic data is to see what it replaces. The three examples below are hypothetical illustrations; every company and organization named in them is invented.
1. Banking Fraud Detection
A regional bank called Harborline Credit modeled its real transaction history, including the rare patterns tied to fraudulent charges, and generated a synthetic transaction dataset. Its data science team used the synthetic version to train and stress-test a fraud model without moving real cardholder records out of the secure environment. The team then evaluated the model against held-out real transactions to check whether the synthetic training data translated into useful fraud detection.
2. Medical Research
A research group at the fictional Westmere Institute modeled patient vitals and treatment timelines, then produced a fully synthetic cohort. After assessing privacy risks and obtaining the necessary approvals, researchers shared that cohort with outside collaborators to develop and test an analysis.
They checked the findings against authorized real data before drawing clinical conclusions.
3. Machine Learning for Retail
An e-commerce startup named Tollgate Market had only a few months of real browsing data. It generated synthetic clickstream and purchase records that matched the patterns of its early traffic, then used the larger synthetic set to explore recommendation models.
As more real data became available, the team evaluated whether those models performed well with actual customers.
Synthetic Data vs. Real Data
Neither kind of data is strictly better; each is useful in different situations.
Real data is preferable when you need ground truth. For models intended to operate on real-world inputs, final evaluation should generally include representative, held-out real data. Audits and clinical reporting may also require original evidence that synthetic records cannot replace.
Synthetic data is useful earlier in development and in sensitive settings. It lets teams build and test before real data is available or approved. In privacy-sensitive domains, it can reduce exposure to real records, and when you need more volume or specific edge cases, it can expand your coverage. The common pattern is to develop on synthetic data and validate on real data.
Want to put synthetic data to work without building a generation pipeline yourself? Learn more about Enov8 DataFactory and how synthetic generation fits into Enov8’s broader test data management solution.