In today’s technology-driven world, IT operations play a critical role in the success of businesses and organizations. One key aspect of IT operations is ensuring that systems and applications are reliable and available when needed.
This is where failure metrics come into play. Failure metrics measure the reliability of IT systems and show teams where to improve.
In this article, we explore three common failure metrics in IT operations: Mean Time to Repair (MTTR), Mean Time Between Failures (MTBF), and Mean Time to Failure (MTTF). We will explain what each metric measures and when it is most useful.
Additionally, we cover each metric’s limits and why you should use all three together.
By the end, you will know how to choose the right failure metrics.
Mean Time to Repair (MTTR)
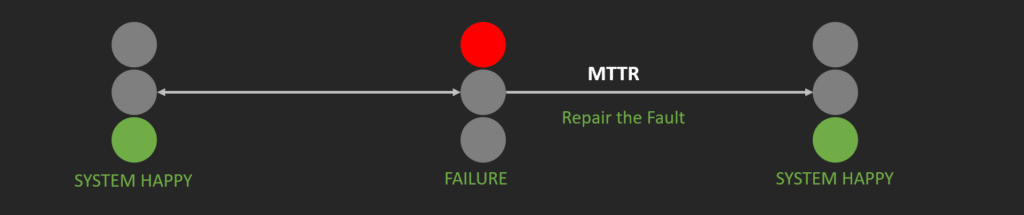
MTTR is a failure metric that measures the average time it takes to repair a system or application after it fails. Incident management teams rely on it because their focus is restoring service fast.
To calculate it, divide total downtime by the number of incidents. For example, 2 hours of downtime across 4 incidents gives an MTTR of 30 minutes.
MTTR is most useful in situations where the primary goal is to minimize the impact of incidents on users or customers. Measuring restore speed helps organizations set realistic downtime expectations and improve response.
However, MTTR has limitations as a failure metric. It does not take into account the frequency or severity of incidents, and it does not provide insight into the underlying causes of failures.
Therefore, use MTTR alongside MTBF and MTTF for a fuller picture.
Mean Time Between Failures (MTBF)
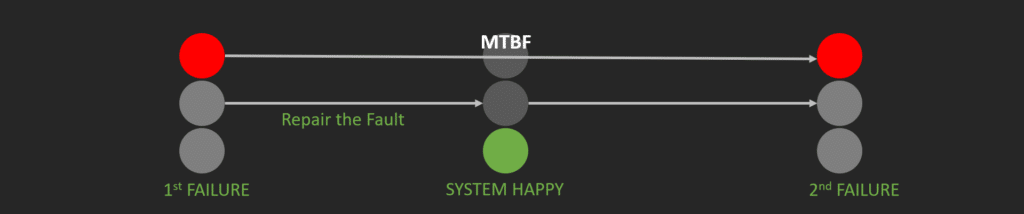
MTBF is a failure metric that measures the average time between system or application failures. Teams use it to predict failures and plan maintenance.
To calculate it, divide total uptime by the number of failures. For example, 100 hours of uptime with 2 failures gives an MTBF of 50 hours.
MTBF is most useful in situations where the primary goal is to prevent failures from occurring. Knowing how often failures occur lets teams plan maintenance and improve reliability.
However, MTBF has limitations as a failure metric. It assumes that failures follow a predictable pattern and that all failures are equal in severity. Additionally, MTBF does not provide insight into how long it takes to repair systems after they fail.
Therefore, use MTBF alongside MTTR and MTTF.
Mean Time to Failure (MTTF)
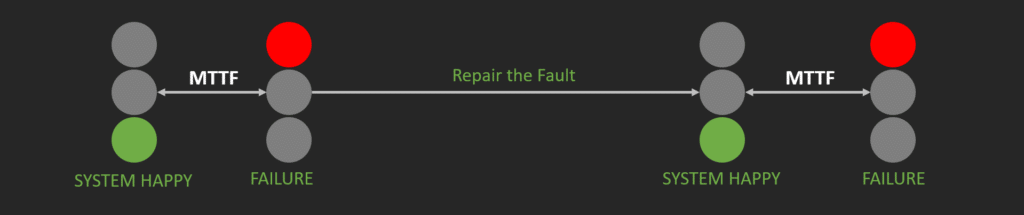
MTTF is a failure metric that measures the average time until a system or application fails. Teams use it to predict how long systems will run before failing.
To calculate it, divide total operating time by the number of failures. For example, 1,000 operating hours with 2 failures gives an MTTF of 500 hours.
MTTF is most useful for predicting failures and planning maintenance.
Knowing how long systems last helps teams plan maintenance and improve reliability.
However, MTTF has limitations as a failure metric. It does not take into account the severity of failures, and it assumes that failures follow a predictable pattern. Additionally, MTTF does not provide insight into how long it takes to repair systems after they fail.
Therefore, use MTTF alongside MTTR and MTBF.
Choosing the Right Failure Metrics
Each metric has strengths and weaknesses. However, together they give a complete view of reliability.
MTTR is most useful for incident management, where the focus is on restoring service as quickly as possible after an incident occurs.
MTBF is most useful for predicting when failures are likely to occur and planning proactive maintenance activities. MTTF is most useful for predicting how long systems can operate before they are likely to fail.
By using all three metrics together, IT teams can gain a more complete picture of system reliability and performance.
For example, a low MTTR with a low MTBF suggests teams fix incidents quickly, but systems fail often. Alternatively, a high MTBF with a low MTTF suggests systems run reliably between failures but fail earlier than expected.
Also, consider your organization’s specific goals when choosing metrics.
For example, if you focus on minimizing downtime, track MTTR first.
Alternatively, if you focus on uptime and maintenance costs, track MTBF and MTTF.
Ultimately, understand each metric’s limits and use them in the way that gives you the most useful insight.
Conclusion
Choosing the right failure metrics is critical for ensuring that IT systems and applications are efficient, reliable, and available when needed.
MTTR, MTBF, and MTTF all measure reliability, but each has its own strengths and weaknesses.
In short, MTTR suits incident management, MTBF predicts failure frequency, and MTTF predicts lifespan.
However, using all three metrics together can provide a more comprehensive understanding of system reliability and performance.
When choosing failure metrics, it’s important to consider the specific needs and goals of your organization.
Used well, they lead to better decisions about maintenance, upgrades, and other IT initiatives.
In summary, by using the right failure metrics, IT teams can ensure that systems and applications are reliable, available, and meet the needs of the organization.
Other Reading
Interested in reading more about Test Environment Management. Why not start here:
Enov8 Blog: Top 5 Cloud Metrics
Enov8 Blog: Top 5 Container Metrics
Medium: Importance of TEM Metrics
Author Andrew Walker
Andrew Walker is a software architect with 10+ years of experience. Andrew is passionate about his craft, and he loves using his skills to design enterprise solutions for Enov8, in the areas of IT Environments, Release & Data Management.