
DevOps brings development and operations together so teams can build and release software faster and more reliably. It leans heavily on collaboration, automation and continuous delivery. Yet one part of the pipeline is often left behind: test data.
Test data is the foundation of software testing. If it isn’t accurate, varied and representative of production, tests miss defects, releases fail and time to market slips. You can automate every build and deployment step, but if teams still wait days for a usable copy of data, the pipeline is only as fast as that wait.
This post explains why test data management (TDM) matters in DevOps, the four main techniques for provisioning test data, and how automation and collaboration bring TDM into a DevOps way of working.
Why Test Data Management Matters in DevOps
Good test data lets developers and testers find and fix defects early, when they are cheapest to fix. Poor test data causes problems that are easy to recognize:
- Not representative. Tests pass in non-production but fail in production, because the data didn’t reflect real-world conditions.
- Not varied enough. Edge cases and unusual scenarios are never tested, so defects slip through.
- Not accurate. Broken or inconsistent records cause false positives and false negatives, wasting time on defects that aren’t real.
- Not secure. Unmasked copies of production put personal data at risk and create compliance exposure.
- Not available. Teams wait for data refreshes, so testing becomes the bottleneck in an otherwise automated pipeline.
Investing in TDM reduces cost, improves software quality and keeps delivery moving, because data stops being the thing everyone waits for.

Test data reservations in Enov8 Test Data Manager
Four Techniques for Effective Test Data Management
Most organizations combine several techniques, depending on the systems involved, the type of testing and their compliance obligations. Here are the four most common, and how Enov8 supports each one.
1. Data Virtualization
Data virtualization, also called data cloning, gives each team its own lightweight, writable copy of a database without making full physical copies. Many teams can work on the same dataset at the same time, and copies can be created, reset or thrown away in minutes rather than hours.
Because virtual copies take a fraction of the storage of full copies, teams can afford to give every developer, tester or pipeline run its own isolated environment.
With Enov8: VirtualizeMe (vME) provides database virtualization, so teams can provision and refresh their own copies of data on demand.
2. Data Masking
Data masking replaces sensitive values, such as names, addresses and account numbers, with realistic but fictitious ones. It reduces the risk of a breach in non-production environments and helps organizations meet privacy regulations such as GDPR and CCPA.
Masking needs to be consistent: the same customer should be masked the same way in every system, so end-to-end tests still line up across applications.
With Enov8: Enov8 Test Data Manager profiles your data to find sensitive fields, masks it consistently across platforms and validates the result, with dashboards showing compliance coverage.
3. Data Subsetting
Data subsetting is the traditional technique of extracting a smaller, representative slice of a production database. Instead of copying terabytes, you take, for example, a set of customers along with all of their related accounts, transactions and history.
The key is referential integrity. A good subset follows the relationships between tables, so every record that’s included brings its related records with it and the application still works as expected. Subsetting brings several benefits:
- Lower storage costs. Smaller databases are cheaper to host, especially across many environments.
- Faster refreshes. A subset can be rebuilt in minutes, so teams get fresh data more often.
- Less sensitive data in circulation. Copying fewer records means less personal data to protect.
- Targeted test data. Subsets can focus on the customers, products or scenarios a team actually needs.
With Enov8: Enov8 DataFactory Prune creates referentially intact subsets of production data, giving teams smaller, faster test datasets without breaking the relationships their applications depend on.
4. Synthetic Data Generation
Synthetic data generation, also called data fabrication, creates artificial data that mimics the structure and characteristics of real data. It is useful when production data doesn’t contain the scenarios you need, such as extreme values, rare combinations or features that haven’t launched yet. It also helps when real data is unavailable, too sensitive to use or too expensive to obtain.
With Enov8: Enov8 DataFactory Bloom generates relational synthetic data from a schema, built-in data skills and your business rules, so teams can fill gaps that production data can’t cover.
Choosing the Right Mix
| Technique | Best for | Enov8 solution |
|---|---|---|
| Data virtualization | Fast, isolated, full-size copies for many teams | VirtualizeMe (vME) |
| Data masking | Protecting personal data in non-production | Enov8 Test Data Manager |
| Data subsetting | Smaller, faster, referentially intact datasets | DataFactory Prune |
| Synthetic data | Scenarios that production data doesn’t cover | DataFactory Bloom |
In practice, these techniques work best together. For example, a team might subset production data, mask the subset, add synthetic records for edge cases and then deliver it through virtual copies, giving every tester a small, safe and fully featured dataset.
Automation and Collaboration in Test Data Management
DevOps moves too fast for manual data requests and hand-built scripts. Bringing TDM into DevOps depends on three practices.
1. Test Data Automation
Automate the creation, masking, subsetting and refreshing of test data so it happens the same way every time. Automation removes human error, shortens wait times and makes test data a repeatable service rather than a one-off project.
2. Collaboration
Developers, testers, DBAs and operations teams all have a stake in test data. Agreeing on shared standards, such as what “representative” means, which fields must be masked and how often data is refreshed, keeps data useful and compliant. Shared visibility, including who is using which dataset and when, also prevents teams from overwriting each other’s work.
3. Continuous Integration and Continuous Delivery (CI/CD)
Make test data provisioning a step in your CI/CD pipeline. When a build is deployed to a test environment, the pipeline can automatically provision a fresh, masked dataset for it. This keeps data current and ensures every test run starts from a known state.
4. Automated Test Data Preparation with DataFactory
Enov8 DataFactory is designed to run as part of the pipeline rather than alongside it. You define a virtual data set once, by connecting a source database or SQL schema and choosing anchor tables, then reuse it for every run.
- Prune cuts a referentially intact subset of production to the size each environment needs, for example 5% of customers with all of their related records.
- Bloom generates synthetic data from schemas, skills and business rules, with a quality check on every run. The same plan and seed produce the same data every time, so a failing test can be reproduced exactly.
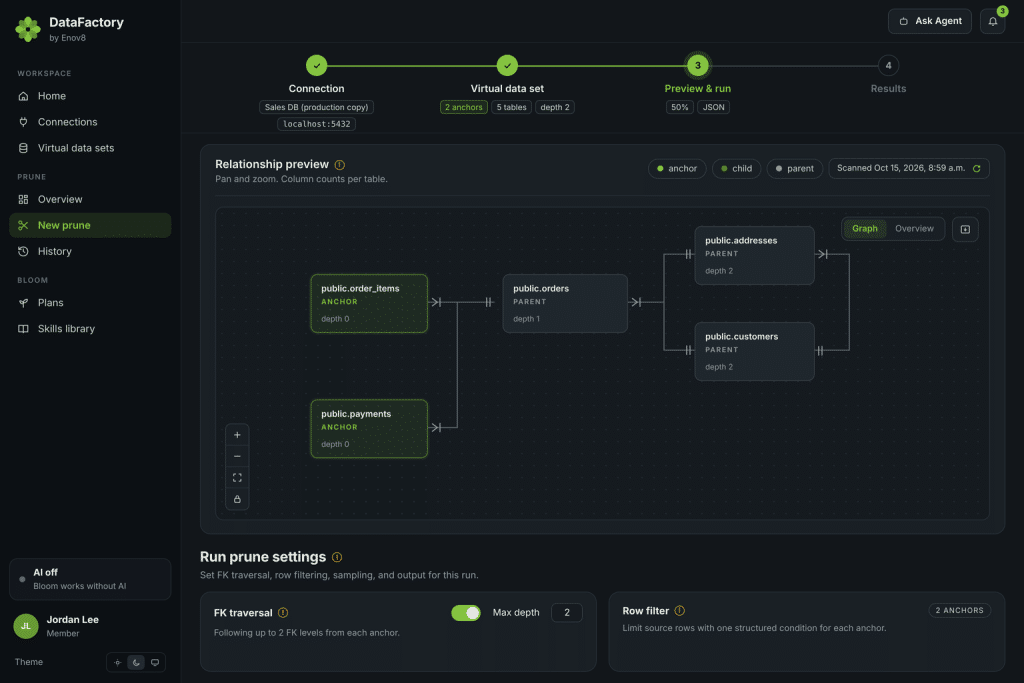
Results can be downloaded as files, loaded straight into a test database, or triggered by your pipelines and AI agents through the API and MCP. DataFactory is self-hosted with Docker, so your data stays on your own infrastructure. A typical pipeline might prune and mask a fresh subset for integration testing, while Bloom adds synthetic edge cases for negative testing.
Need smaller test databases, or realistic data without production records?
Discover how Enov8 DataFactory Prune reduces database size while preserving referential integrity, and how DataFactory Bloom generates relational synthetic data from schemas, skills and business rules.
Conclusion
Test data is too often the slowest part of a DevOps pipeline. Accurate, varied and secure test data helps teams find defects early, release with confidence and avoid compliance risk.
No single technique solves every problem. Virtualization gives teams fast, isolated copies. Masking protects sensitive information. Subsetting keeps datasets small and fast while preserving their relationships. Synthetic data fills the gaps production can’t. Automation and collaboration tie these together so test data keeps pace with the rest of the pipeline.
Enov8 brings these capabilities together: Enov8 Test Data Manager for masking and compliance, Enov8 DataFactory for subsetting (Prune) and synthetic data (Bloom), and VirtualizeMe (vME) for database virtualization.
Further Reading
- What Is a Test Data Manager? A Complete Guide
- Test Data Management Strategy Design: Guide and Best Practices
- Why Is Test Data Management So Important?
- Database Provisioning: What It Is and How It Works
Author Andrew Walker
Andrew Walker is a software architect with 10+ years of experience. Andrew is passionate about his craft, and he loves using his skills to design enterprise solutions for Enov8, in the areas of IT Environments, Release & Data Management.